引言
特征工程是机器学习中最重要也最费力的环节。一个好的特征往往比换模型更有效,但这一步通常会产生充满嵌套循环、手工索引和硬编码组合的混乱代码。
Python 的 itertools 模块是标准库中的迭代器工具箱——大多数数据科学家知道它存在,但真正在特征工程中用它的人很少。这是个遗憾,因为特征工程的本质就是结构化迭代:遍历变量对、滑动窗口、分组序列、特征子集……而 itertools 正是为此而生。
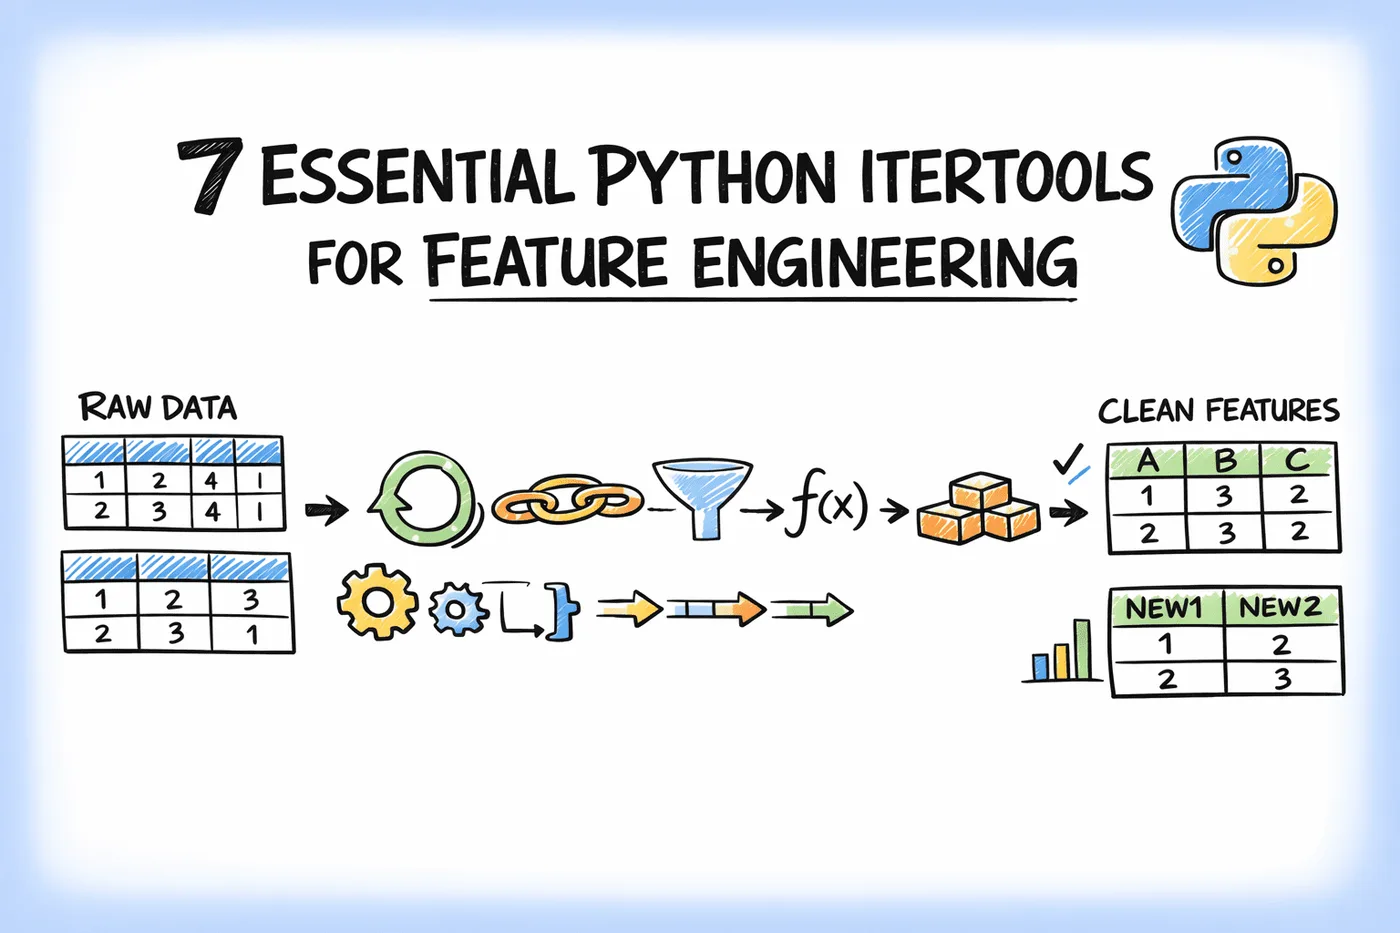
本文用 7 个函数解决常见特征工程问题,以电商数据为例,涵盖交互特征、滑动窗口、类别组合等场景。文中代码可在 GitHub 获取。
1. combinations:生成交互特征
交互特征捕捉两个变量之间的关系——这是单个变量无法表达的信号。手动列出多列数据集的每一对组合非常繁琐,combinations 一行搞定。
import itertools
import pandas as pd


df = pd.DataFrame({
    "avg_order_value":    [142.5, 89.0, 210.3, 67.8, 185.0],
    "discount_rate":      [0.10,  0.25, 0.05,  0.30, 0.15],
    "days_since_signup":  [120,   45,   380,   12,   200],
    "items_per_order":    [3.2,   1.8,  5.1,   1.2,  4.0],
    "return_rate":        [0.05,  0.18, 0.02,  0.22, 0.08],
})


numeric_cols = df.columns.tolist()


for col_a, col_b in itertools.combinations(numeric_cols, 2):
    feature_name = f"{col_a}_x_{col_b}"
    df[feature_name] = df[col_a] * df[col_b]


interaction_cols = [c for c in df.columns if "_x_" in c]
print(df[interaction_cols].head())
输出(截取):
avg_order_value_x_discount_rate  avg_order_value_x_days_since_signup  ...
0                           14.250                              17100.0   ...
1                           22.250                               4005.0   ...
combinations(numeric_cols, 2) 生成每对唯一组合,不含重复。5 列生成 10 对,10 列生成 45 对,随列数自动扩展。
2. product:构建跨类别特征网格
itertools.product 计算两个或多个可迭代对象的笛卡尔积——跨组的所有可能组合。
在电商场景中,这适合构建「用户分层 × 商品类别 × 渠道」的特征查找矩阵:
import itertools
import numpy as np


customer_segments = ["new", "returning", "vip"]
product_categories = ["electronics", "apparel", "home_goods", "beauty"]
channels = ["mobile", "desktop"]


combos = list(itertools.product(customer_segments, product_categories, channels))


grid_df = pd.DataFrame(combos, columns=["segment", "category", "channel"])


np.random.seed(7)
grid_df["avg_conversion_rate"] = np.round(
    np.random.uniform(0.02, 0.18, size=len(grid_df)), 3
)


print(grid_df.head(12))
print(f"\nTotal combinations: {len(grid_df)}")
输出:
segment     category  channel  avg_conversion_rate
0         new  electronics   mobile                0.032
1         new  electronics  desktop                0.145
...
Total combinations: 24
这张网格可以 merge 回主交易表,作为查找特征——每行都获得其对应 segment × category × channel 组合的预期转化率。
3. chain:合并多来源特征列表
在真实 Pipeline 中,特征往往来自多个来源:用户表、商品表、行为表。chain 把它们展平成一个统一的特征列表:
import itertools


customer_features = [
    "customer_age", "days_since_signup", "lifetime_value",
    "total_orders", "avg_order_value"
]


product_features = [
    "category", "brand_tier", "avg_rating",
    "review_count", "is_sponsored"
]


behavioral_features = [
    "pages_viewed_last_7d", "search_queries_last_7d",
    "cart_abandonment_rate", "wishlist_size"
]


all_features = list(itertools.chain(
    customer_features,
    product_features,
    behavioral_features
))


print(f"Total features: {len(all_features)}")
print(all_features)
输出:
Total features: 14
['customer_age', 'days_since_signup', ..., 'wishlist_size']
简单场景下 + 拼接列表也行,但 chain 在来源很多、部分来源是生成器、或特征组需要条件组合时更具优势,代码可读性和可组合性更好。
4. islice:构建滑动窗口滞后特征
滞后特征在很多数据集中都很重要:上月消费额、最近 3 次订单数量、最近 5 次平均客单价……手动用索引构建这些特征容易出错。
islice 可以在不转换为列表的情况下对迭代器切片,适合逐行处理有序交易历史:
import itertools


transactions = [
    {"order_id": "ORD-8821", "amount": 134.50, "items": 3},
    {"order_id": "ORD-8934", "amount":  89.00, "items": 2},
    {"order_id": "ORD-9102", "amount": 210.75, "items": 5},
    {"order_id": "ORD-9341", "amount":  55.20, "items": 1},
    {"order_id": "ORD-9488", "amount": 178.90, "items": 4},
    {"order_id": "ORD-9601", "amount": 302.10, "items": 7},
]


window_size = 3
features = []


for i in range(window_size, len(transactions)):
    window = list(itertools.islice(transactions, i - window_size, i))
    current = transactions[i]


    lag_amounts = [t["amount"] for t in window]
    features.append({
        "order_id":       current["order_id"],
        "current_amount": current["amount"],
        "lag_1_amount":   lag_amounts[-1],
        "lag_2_amount":   lag_amounts[-2],
        "lag_3_amount":   lag_amounts[-3],
        "rolling_mean_3": round(sum(lag_amounts) / len(lag_amounts), 2),
        "rolling_max_3":  max(lag_amounts),
    })


print(pd.DataFrame(features).to_string(index=False))
输出:
order_id  current_amount  lag_1_amount  lag_2_amount  lag_3_amount  rolling_mean_3  rolling_max_3
ORD-9341            55.2        210.75         89.00        134.50          144.75         210.75
ORD-9488           178.9         55.20        210.75         89.00          118.32         210.75
ORD-9601           302.1        178.90         55.20        210.75          148.28         210.75
islice(transactions, i - window_size, i) 精确截取前 window_size 条记录,无需为完整历史构建中间列表。
5. groupby:按类别聚合特征
groupby 对排序后的可迭代对象分组,计算每组统计量。
同一客户在不同商品类别上的消费行为差异很大——把所有订单混在一起会丢失这个信号。
重要:itertools.groupby 必须先按 key 排序,与 pandas groupby 不同,它只对连续元素分组。
import itertools


orders = [
    {"customer": "C-10482", "category": "electronics", "amount": 349.99},
    {"customer": "C-10482", "category": "electronics", "amount": 189.00},
    {"customer": "C-10482", "category": "apparel",     "amount":  62.50},
    {"customer": "C-10482", "category": "apparel",     "amount":  88.00},
    {"customer": "C-10482", "category": "apparel",     "amount":  45.75},
    {"customer": "C-10482", "category": "home_goods",  "amount": 124.30},
]


orders_sorted = sorted(orders, key=lambda x: x["category"])


category_features = {}
for category, group in itertools.groupby(orders_sorted, key=lambda x: x["category"]):
    amounts = [o["amount"] for o in group]
    category_features[category] = {
        "order_count": len(amounts),
        "total_spend": round(sum(amounts), 2),
        "avg_spend":   round(sum(amounts) / len(amounts), 2),
        "max_spend":   max(amounts),
    }


cat_df = pd.DataFrame(category_features).T
cat_df.index.name = "category"
print(cat_df)
输出:
order_count  total_spend  avg_spend  max_spend
category
apparel              3.0       196.25      65.42      88.00
electronics          2.0       538.99     269.50     349.99
home_goods 1.0 124.30 124.30 124.30这些按类别的聚合结果最终成为用户行的特征列:electronics_avg_spend、apparel_order_count 等。
6. combinations_with_replacement:多项式特征
多项式特征(平方、立方、交叉项)是让线性模型具备捕捉非线性关系能力的标准方法。
与 combinations 的区别在于:combinations_with_replacement 允许同一元素出现两次,从而产生平方项(如 avg_order_value^2):
import itertools


df_poly = pd.DataFrame({
    "avg_order_value": [142.5, 89.0, 210.3, 67.8],
    "discount_rate":   [0.10,  0.25, 0.05,  0.30],
    "items_per_order": [3.2,   1.8,  5.1,   1.2],
})


cols = df_poly.columns.tolist()


for col_a, col_b in itertools.combinations_with_replacement(cols, 2):
    feature_name = f"{col_a}^2" if col_a == col_b else f"{col_a}_x_{col_b}"
    df_poly[feature_name] = df_poly[col_a] * df_poly[col_b]


poly_cols = [c for c in df_poly.columns if "^2" in c or "_x_" in c]
print(df_poly[poly_cols].round(3))
输出:
avg_order_value^2  avg_order_value_x_discount_rate  ...  items_per_order^2
0           20306.25                           14.250  ...              10.24
1            7921.00                           22.250  ...               3.24
不需要引入 scikit-learn 的 PolynomialFeatures,同时可以精确控制哪些特征参与展开。
7. accumulate:累计行为特征
itertools.accumulate 对序列计算运行时累计聚合,无需 pandas 或 NumPy。
累计特征(累计消费、累计订单数、滚动平均客单价)对终身价值建模和流失预测很有价值:
import itertools


order_amounts = [56.80, 123.40, 89.90, 245.00, 67.50, 310.20, 88.75]


cumulative_spend = list(itertools.accumulate(order_amounts))
cumulative_max   = list(itertools.accumulate(order_amounts, func=max))
cumulative_count = list(itertools.accumulate([1] * len(order_amounts)))


features_df = pd.DataFrame({
    "order_number":        range(1, len(order_amounts) + 1),
    "order_amount":        order_amounts,
    "cumulative_spend":    cumulative_spend,
    "cumulative_max_order": cumulative_max,
    "order_count_so_far":  cumulative_count,
})


features_df["avg_spend_so_far"] = (
    features_df["cumulative_spend"] / features_df["order_count_so_far"]
).round(2)


print(features_df.to_string(index=False))
输出:
order_number  order_amount  cumulative_spend  cumulative_max_order  order_count_so_far  avg_spend_so_far
            1         56.80             56.80                  56.8                   1             56.80
            2        123.40            180.20                 123.4                   2             90.10
            3         89.90            270.10                 123.4                   3             90.03
            4        245.00            515.10                 245.0                   4            128.78
            5         67.50            582.60                 245.0                   5            116.52
            6        310.20            892.80                 310.2                   6            148.80
            7         88.75            981.55                 310.2                   7            140.22
accumulate 支持自定义 func 参数——max、min、operator.mul 或自定义 lambda 均可。每一行是客户在该时间点的历史快照,适合构建序列模型的特征或避免数据泄露的训练数据。
总结
7 个函数速查表:
函数 | 特征工程用途 |
| 两两交互特征 |
| 跨类别特征网格 |
| 合并多来源特征列表 |
| 滞后与滑动窗口特征 |
| 按组聚合特征 |
| 多项式 / 平方特征 |
| 累计行为特征 |
培养一个好习惯:当特征工程问题本质上是一个迭代问题时,itertools 几乎总是比手写循环提供更干净的答案。
参考资料